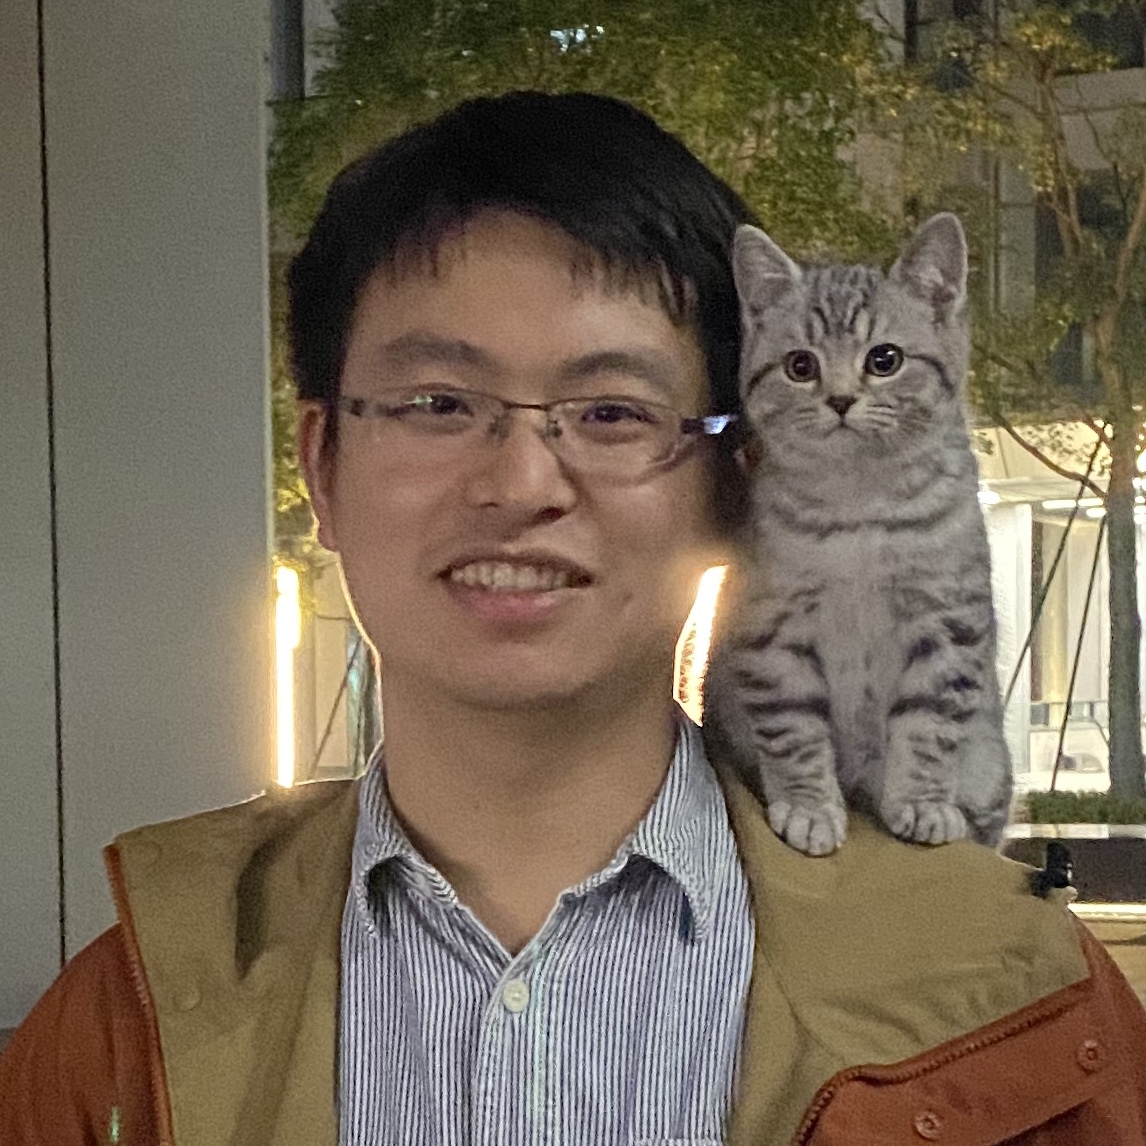
Xue Yang
Assistant Professor, Ph.D. Supervisor
School of Automation and Intelligent Sensing, Shanghai Jiao Tong University
800 Dongchuan Road, Shanghai, 200240, China
📧 [email protected], [email protected], [email protected]
我正在寻找自驱力较强的攻读硕/博士 (2028年保研、拿到创智/中关村/河套等国家AI学院offer,提前进组实习是必须的,越早越好) 的学生、实习生(长期招收),与严骏驰教授共同指导,目标是在智能体、多模态大模型、空间智能、遥感影像解译等课题上做出有影响力的工作。请随时通过电子邮件与我联系。
Looking for self-motivated students (Master/Ph.D. 2028 spring & fall), interns to join us, co-supervised by Prof. Junchi Yan, with the goal of doing impactful work on the topic of Agentic AI, Multimodal Large Language Model, Spatial Intelligence, Remote Sensing Image Interpretation, etc. Please do not hesitate to contact me via email.
🔑 Research Interests
My research Citations: 13958 interests include Agentic AI, Multimodal Large Language Model, Spatial Intelligence, Remote Sensing Image Interpretation, etc.
2026-09
Seven papers are accepted by NeurIPS 2026, including two Spotlight Main track papers (292/30709=0.95%) and one Spotlight ED track paper (33/3757=0.88%). Congratulations! 🎉🎉🎉
2026-09
I will serve as Area Chair for CVPR 2027
2026-09
One paper related to VLM (RSTalker) is accepted by IEEE TGRS
2026-09
The World Model Benchmark TriWorldBench competition is in full swing.🔥🔥🔥
2026-08
Serving as a member of the First World Model Committee of the CIE (Chinese Institute of Electronics). 🎉🎉🎉
2026-08
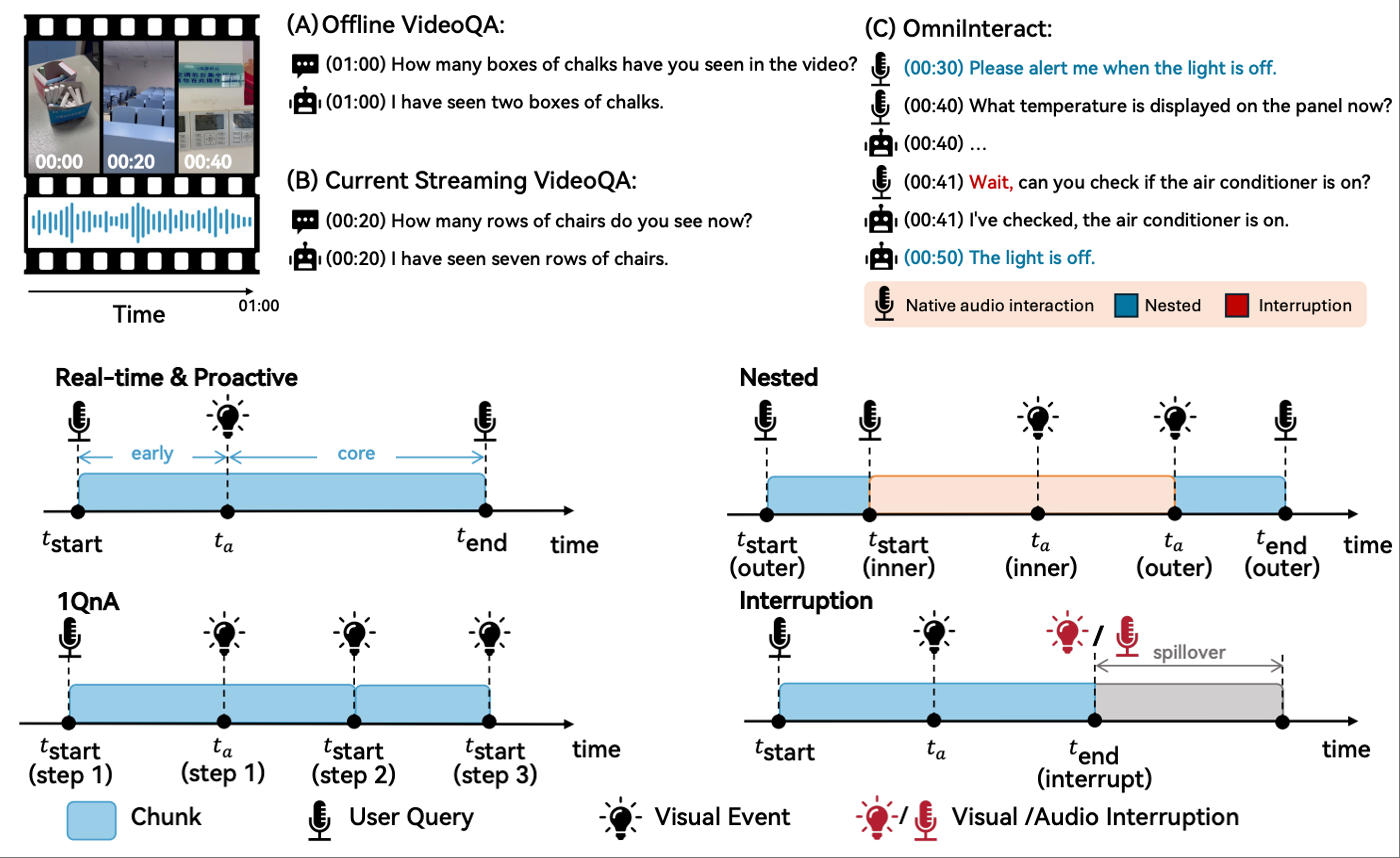
One paper related to Streaming Video (OmniInteract) is accepted by EMNLP 2026. Congratulations to Xudong Lu and Xueying Li. 🎉🎉🎉
2026-08
I will serve as Area Chair for ICLR 2027
2026-08
The project on agent self-evolution has been selected for the 2026 CAAI-Ant Research Fund (AGI Special Program),23/240+<10%. 🚀🚀🚀
2026-08
Serves as Chief Scientist at COOWA. 🚀🚀🚀
2026-07
Congratulations to Zhaokai Wang on being selected for the Chinese Institute of Electronics-Tencent Large Model Doctoral Research Incentive Program (Hunyuan Doctoral Special Program), 中国电子学会-腾讯大模型博士生科研激励计划(混元博士生专项). 🧨🧨🧨
2026-07
GRADE (ECCV 2026) is accepted as Oral. 🚀🚀🚀
2026-06
I will serve as Senior Program Committee for AAAI 2027
2026-06
Four papers related to VLM (GRADE, EvoTok), Visual Grounding (RGBT-GroundBench) and Continual Learning (SCL-MGSM) are accepted by ECCV 2026. Congratulations to Mingxin Liu, Ziqian Fan (Sophomore), Zhaokai Wang, Leyao Gu (Sophomore), Zirun Zhu (Sophomore), Yan Li, Ning Liao, Ruilin Li. 🎉🎉🎉
2026-05
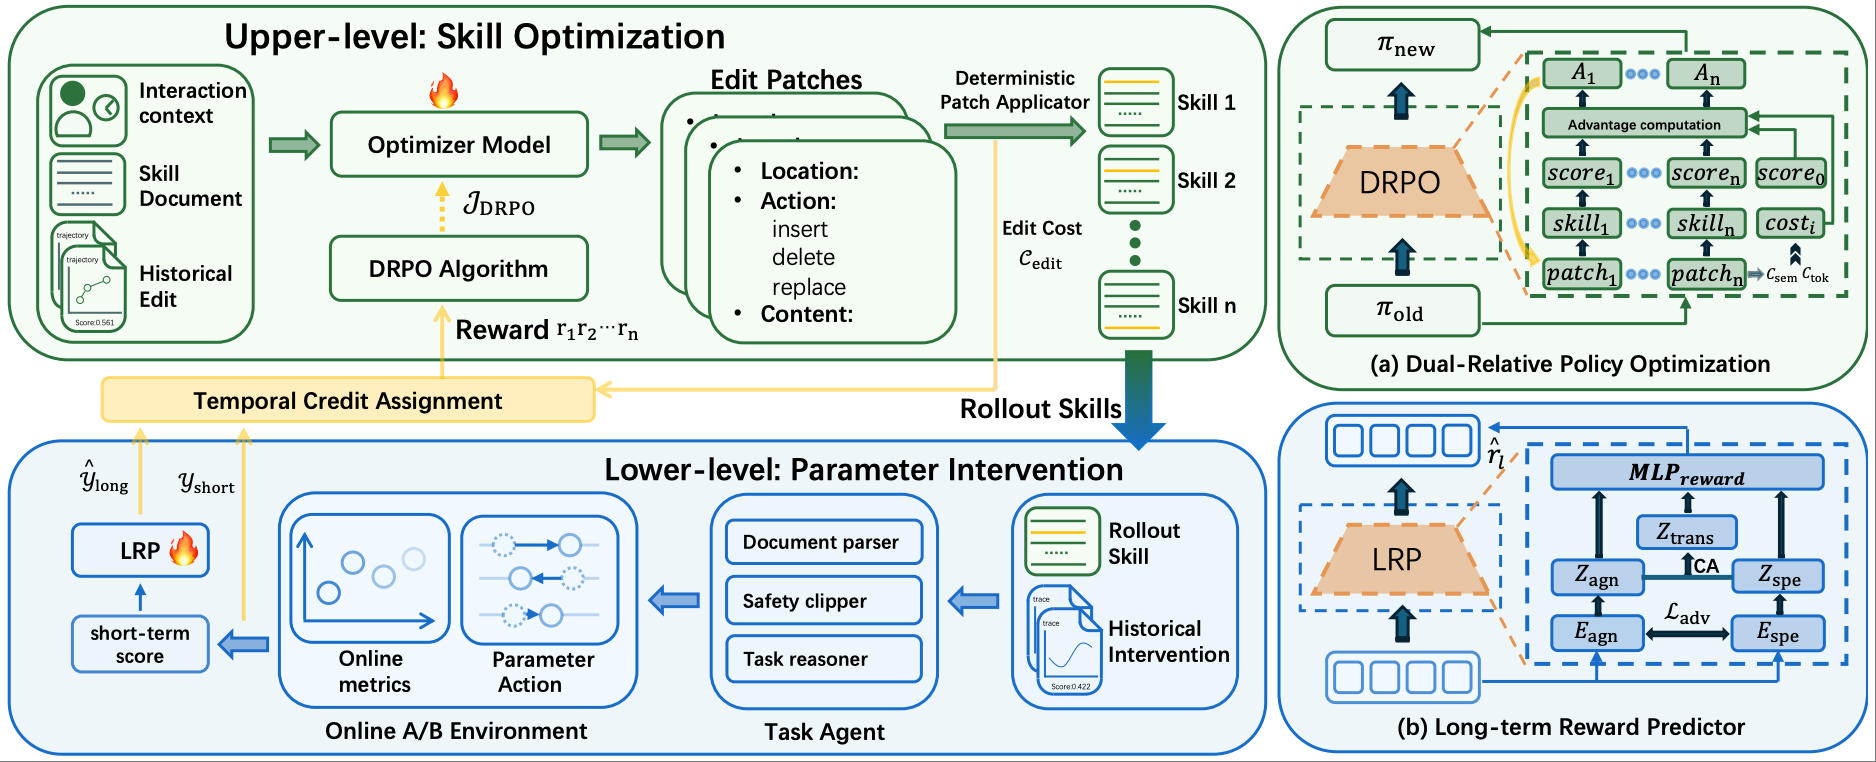
We have open-sourced SkillOpt 
2026-05
Congratulations to doctoral student Ziyang Gong for receiving the first CCF doctoral student funding program. 🧨🧨🧨